


[2024] Pass Databricks-Machine-Learning-Professional Exam - Real Questions and Answers
Databricks-Machine-Learning-Professional Exam Questions Get Updated [2024] with Correct Answers
NEW QUESTION # 33
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a series of runs for the experiment with experiment ID exp_id, the data scientist wants to programmatically work with the experiment run data in a Spark DataFrame. They have an active MLflow Client client and an active Spark session spark.
Which of the following lines of code can be used to obtain run-level results for exp_id in a Spark DataFrame?
- A. mlflow.search_runs(exp_id)
- B. spark.read.format("mlflow-experiment").load(exp_id)
- C. client.list_run_infos(exp_id)
- D. spark.read.format("delta").load(exp_id)
- E. There is no way to programmatically return row-level results from an MLflow Experiment.
Answer: D
NEW QUESTION # 34
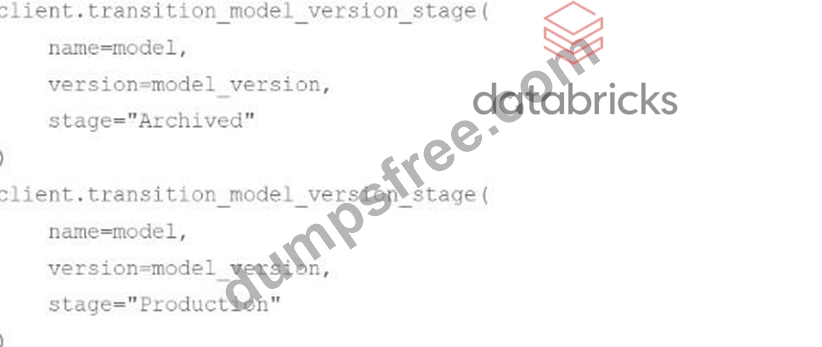
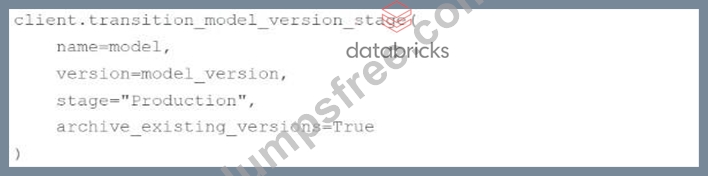
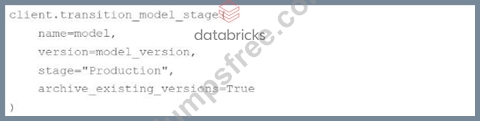
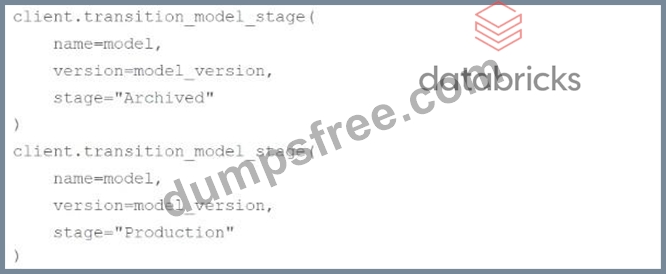
A machine learning engineer wants to move their model version model_version for the MLflow Model Registry model model from the Staging stage to the Production stage using MLflow Client client. At the same time, they would like to archive any model versions that are already in the Production stage.
Which of the following code blocks can they use to accomplish the task?
- A.
- B.
- C.
- D.
Answer: C
NEW QUESTION # 35
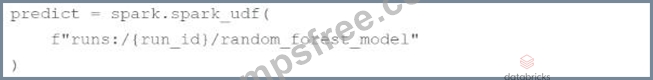
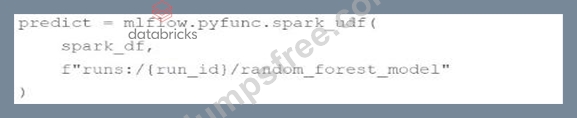
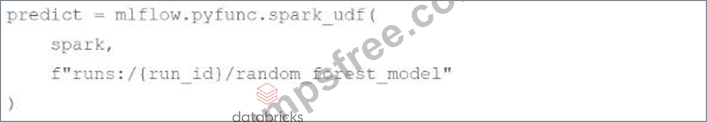
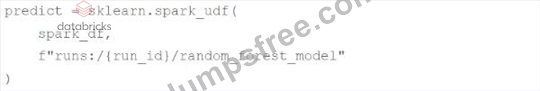
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable. They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df.
Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
- A.
- B.
- C.
- D.
- E. It is not possible to deploy a scikit-learn model on a Spark DataFrame.
Answer: A
NEW QUESTION # 36
Which of the following MLflow Model Registry use cases requires the use of an HTTP Webhook?
- A. None of these use cases require the use of an HTTP Webhook
- B. Updating data in a source table for a Databricks SQL dashboard when a model version transitions to the Production stage
- C. Sending a message to a Slack channel when a model version transitions stages
- D. Sending an email alert when an automated testing Job fails
- E. Starting a testing job when a new model is registered
Answer: B
NEW QUESTION # 37
A data scientist has written a function to track the runs of their random forest model. The data scientist is changing the number of trees in the forest across each run.
Which of the following MLflow operations is designed to log single values like the number of trees in a random forest?
- A. mlflow.log_param
- B. mlflow.log_artifact
- C. mlflow.log_metric
- D. mlflow.log_model
- E. There is no way to store values like this.
Answer: C
NEW QUESTION # 38
Which of the following is a simple statistic to monitor for categorical feature drift?
- A. Mode, number of unique values, and percentage of missing values
- B. Percentage of missing values
- C. Mode
- D. Number of unique values
- E. None of these
Answer: A
NEW QUESTION # 39
A data scientist would like to enable MLflow Autologging for all machine learning libraries used in a notebook. They want to ensure that MLflow Autologging is used no matter what version of the Databricks Runtime for Machine Learning is used to run the notebook and no matter what workspace-wide configurations are selected in the Admin Console.
Which of the following lines of code can they use to accomplish this task?
- A. It is not possible to automatically log MLflow runs.
- B. spark.conf.set("autologging", True)
- C. mlflow.autolog()
- D. mlflow.spark.autolog()
- E. mlflow.sklearn.autolog()
Answer: B
NEW QUESTION # 40
Which of the following MLflow operations can be used to automatically calculate and log a Shapley feature importance plot?
- A. client.log_artifact
- B. mlflow.shap
- C. None of these operations can accomplish the task.
- D. mlflow.shap.log_explanation
- E. mlflow.log_figure
Answer: B
NEW QUESTION # 41
After a data scientist noticed that a column was missing from a production feature set stored as a Delta table, the machine learning engineering team has been tasked with determining when the column was dropped from the feature set.
Which of the following SQL commands can be used to accomplish this task?
- A. DESCRIBE
- B. TIMESTAMP
- C. VERSION
- D. DESCRIBE HISTORY
- E. HISTORY
Answer: D
NEW QUESTION # 42
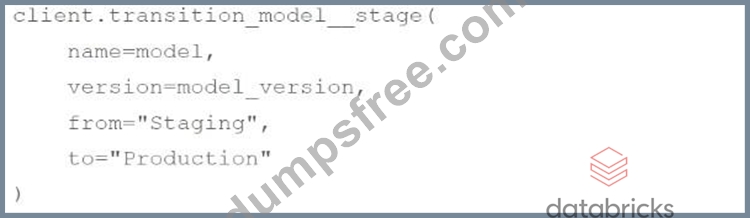
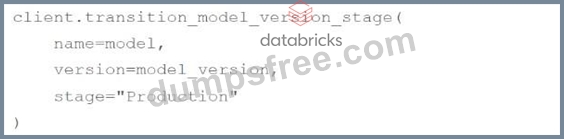
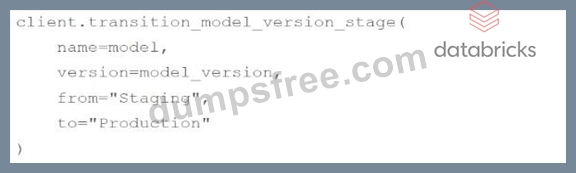
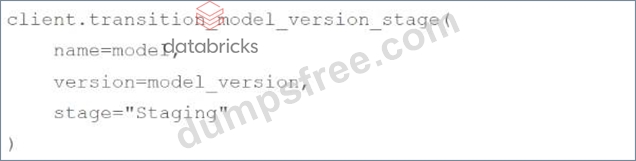
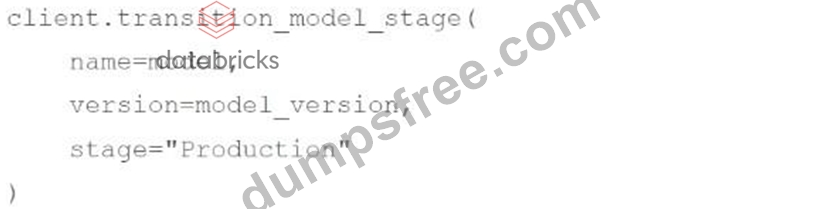
A machine learning engineer wants to move their model version model_version for the MLflow Model Registry model model from the Staging stage to the Production stage using MLflow Client client.
Which of the following code blocks can they use to accomplish the task?
- A.
- B.
- C.
- D.
- E.
Answer: D
NEW QUESTION # 43
Which of the following MLflow operations can be used to delete a model from the MLflow Model Registry?
- A. client.delete_model_version
- B. client.delete_model
- C. client.delete_registered_model
- D. client.transition_model_version_stage
- E. client.update_registered_model
Answer: C
NEW QUESTION # 44
A machine learning engineer is using the following code block as part of a batch deployment pipeline: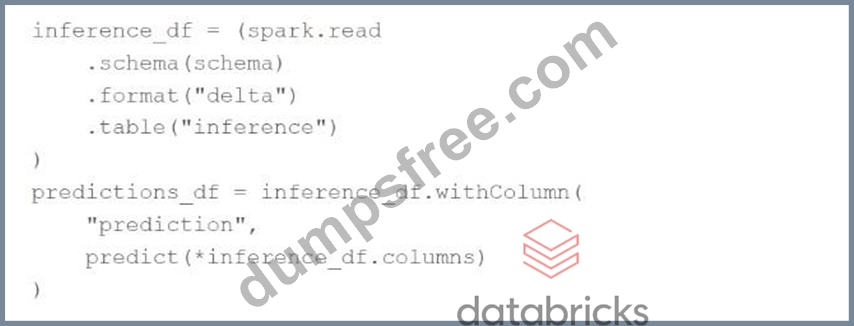
Which of the following changes needs to be made so this code block will work when the inference table is a stream source?
- A. Replace schema(schema) with option("maxFilesPerTriqqer", 1}
- B. Replace "inference" with the path to the location of the Delta table
- C. Replace predict with a stream-friendly prediction function
- D. Replace formatfdelta") with format("stream")
- E. Replace spark.read with spark.readStream
Answer: A
NEW QUESTION # 45
Which of the following is a simple, low-cost method of monitoring numeric feature drift?
- A. None of these can be used to monitor feature drift
- B. Chi-squared test
- C. Kolmogorov-Smirnov (KS) test
- D. Summary statistics trends
- E. Jensen-Shannon test
Answer: D
NEW QUESTION # 46
Which of the following is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov-Smirnov (KS) test for numeric feature drift detection?
- A. JS does not require any manual threshold or cutoff determinations
- B. JS is more robust when working with large datasets
- C. All of these reasons
- D. None of these reasons
- E. JS is not normalized or smoothed
Answer: B
NEW QUESTION # 47
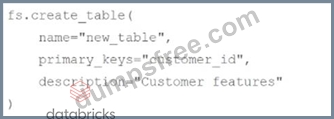
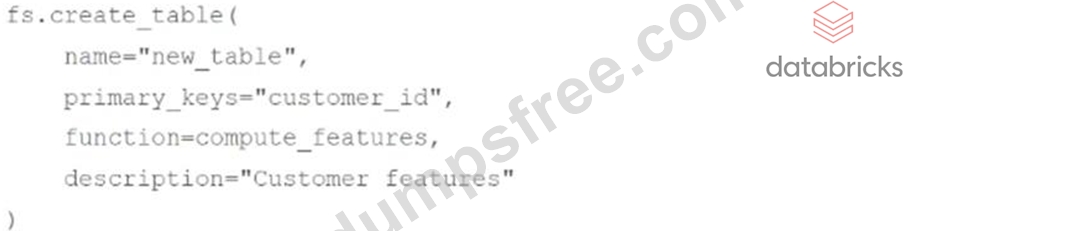
A data scientist has created a Python function compute_features that returns a Spark DataFrame with the following schema: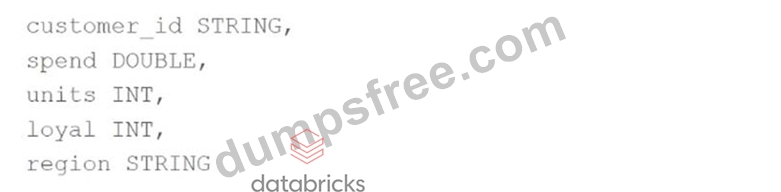
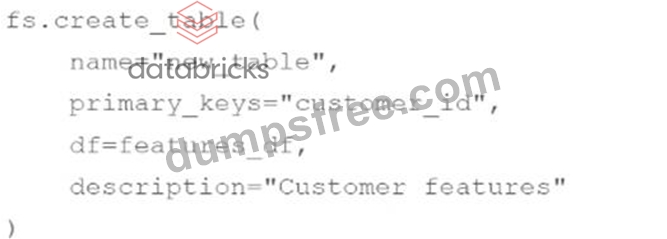
The resulting DataFrame is assigned to the features_df variable. The data scientist wants to create a Feature Store table using features_df.
Which of the following code blocks can they use to create and populate the Feature Store table using the Feature Store Client fs?
- A. features_df.write.mode("fs").path("new_table")
- B.
- C.
- D. features_df.write.mode("feature").path("new_table")
- E.
Answer: E
NEW QUESTION # 48
A machine learning engineer is attempting to create a webhook that will trigger a Databricks Job job_id when a model version for model model transitions into any MLflow Model Registry stage.
They have the following incomplete code block: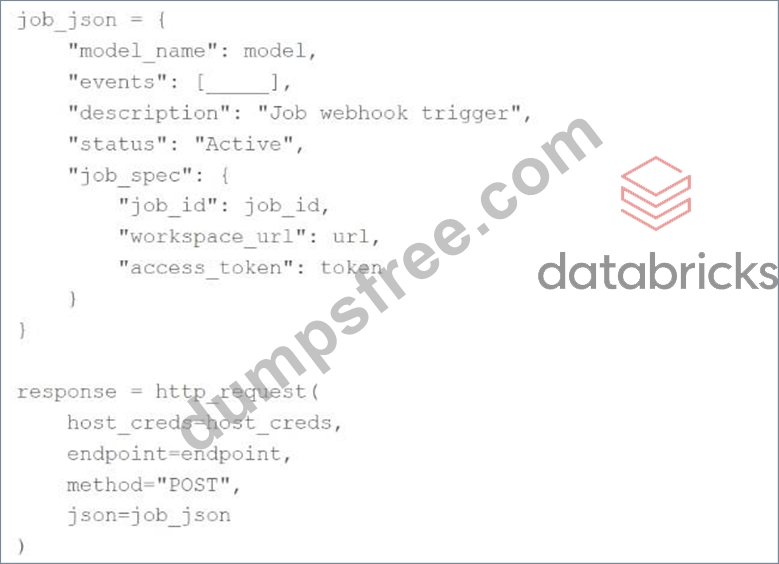
Which of the following lines of code can be used to fill in the blank so that the code block accomplishes the task?
- A. "MODEL_VERSION_CREATED"
- B. "MODEL_VERSION_TRANSITIONED_STAGE"
- C. "MODEL_VERSION_TRANSITIONED_TO_PRODUCTION"
- D. "MODEL_VERSION_TRANSITIONED_TO_STAGING"
- E. "MODEL_VERSION_TRANSITIONED_TO_STAGING", "MODEL_VERSION_TRANSITIONED_TO_PRODUCTION"
Answer: D
NEW QUESTION # 49
Which of the following is a probable response to identifying drift in a machine learning application?
- A. None of these responses
- B. Retraining and deploying a model on more recent data
- C. Rebuilding the machine learning application with a new label variable
- D. All of these responses
- E. Sunsetting the machine learning application
Answer: A
NEW QUESTION # 50
A data scientist set up a machine learning pipeline to automatically log a data visualization with each run. They now want to view the visualizations in Databricks.
Which of the following locations in Databricks will show these data visualizations?
- A. Logged data visualizations cannot be viewed in Databricks
- B. The Artifacts section of the MLflow Experiment page
- C. The Figures section of the MLflow Run page
- D. The Artifacts section of the MLflow Run page
- E. The MLflow Model Registry Model paqe
Answer: C
NEW QUESTION # 51
......
Databricks Databricks-Machine-Learning-Professional Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
| Topic 6 |
|
| Topic 7 |
|
| Topic 8 |
|
| Topic 9 |
|
| Topic 10 |
|
Practice Databricks-Machine-Learning-Professional Questions With Certification guide Q&A from Training Expert DumpsFree: https://www.dumpsfree.com/Databricks-Machine-Learning-Professional-valid-exam.html
Free Databricks Databricks-Machine-Learning-Professional Test Practice Test Questions Exam Dumps: https://drive.google.com/open?id=1S55G2f48IgwrsRzF5lBKKMyqbiGJGmbV